AI-Written Code Reached 17.25% of Linux Kernel Patches in September
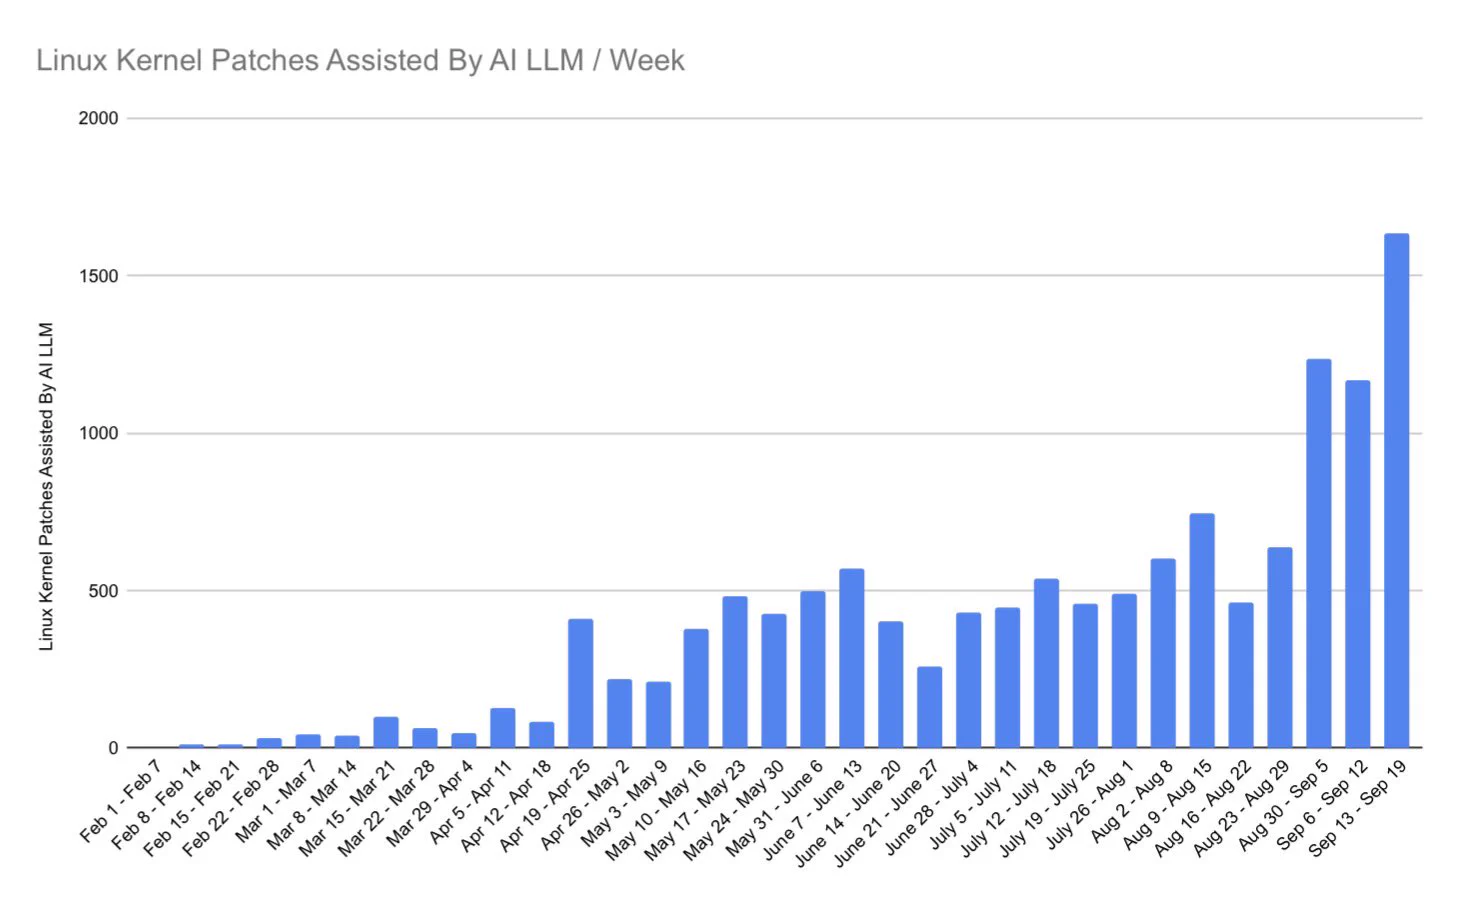
A Lunduke Journal count puts AI-generated contributions at roughly one in six Linux kernel patches for September, though the methodology behind the number has not been published.
Roughly one in six Linux kernel patches submitted in September contained AI-generated code, according to a tally published by the Lunduke Journal. The figure, 17.25%, is being treated by kernel watchers as the first concrete number for how far machine-written contributions have spread into core systems software. If it holds, AI authorship has moved well past the experimental stage inside a project that underpins most of the world's servers, phones and cloud infrastructure.
The number arrives with little public methodology attached. The Lunduke Journal post does not spell out how it separated machine-written lines from human ones, whether it counted whole patches or mixed diffs, or which kernel trees it sampled. That gap matters because kernel development already blends human and tool-generated output: Coccinelle semantic patches, checkpatch cleanups and other scripted rewrites have produced mechanically generated changes for years. Telling those apart from output produced by a large language model is not a trivial classification problem.
There is also the question of what counts as an AI patch. A developer who asks a model to draft a driver fix and then reviews, edits and signs off on it is still the author of record under the kernel's Developer Certificate of Origin. Kernel maintainers have grown louder about disclosure in recent months, with some subsystem trees asking contributors to state when a model wrote code they are submitting. Linus Torvalds has not set a project-wide rule, leaving each maintainer to decide how much disclosure to demand.
The kernel's review pipeline is the real filter. Every patch runs through mailing lists, subsystem maintainers and automated build and boot testing before it lands, so low-quality machine output tends to get caught or dropped rather than merged. That is why the 17.25% figure, even if imprecise, is less alarming to veterans than it sounds: the process is designed to reject changes that break things, regardless of who or what wrote them. What it does not catch is the slower cost, which is reviewer time spent reading plausible-looking patches that turn out to be wrong.
The broader signal is that AI assistance has moved from autocomplete to a measurable share of commits in one of the most conservative codebases in existence. Other large projects have reported similar upward trends, but few have published a percentage tied to a specific month. If the kernel number is anywhere close to right, it sets a baseline that other maintainers will be measured against, and it pressures the project to settle on disclosure norms before the share climbs further.
What to watch next is whether anyone replicates the count with a published method. A credible breakdown by subsystem, by author and by whether the AI involvement was disclosed would turn a single tweet-sized statistic into something maintainers can actually act on. Until then, the 17.25% figure is best read as a prompt for the kernel community to decide how it wants to count, label and review machine-written code.