A Capital Letter, Not the Model, Was Breaking This AI Support Bot
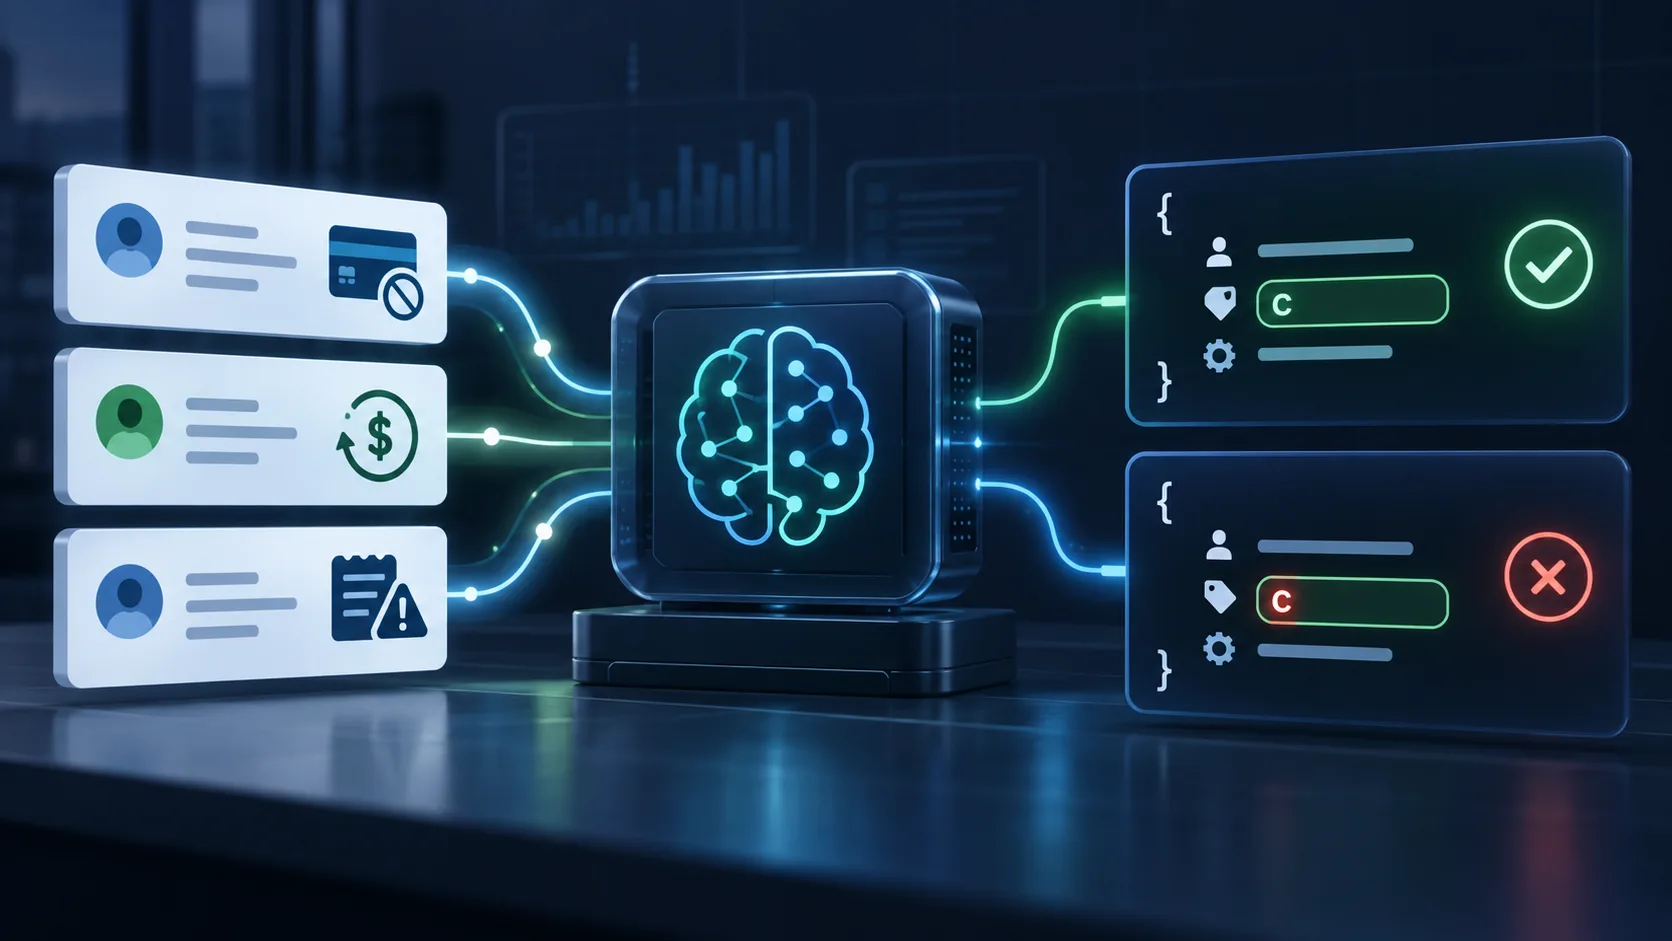
A Weave regression test across three OpenAI models traced a customer-support failure to reply formatting, not model quality.
A developer building a customer-support bot traced a recurring failure to a single capital letter in the model's output, not to the underlying model itself. The case, documented in a Weave project that regression-tests three OpenAI models against one exact reply format, shows how a formatting quirk can take down an application that otherwise works. The finding matters because teams tend to blame the newest model when an integration breaks, and this one did not come from the new model at all.
The setup was straightforward. The bot needed replies in a fixed shape, and the developer ran the same prompts through three OpenAI models to see which ones held that shape. Weave, the evaluation and observability tool, handled the comparison so the outputs could be checked side by side rather than eyeballed one at a time. That structure is what made the culprit visible: the failures clustered around formatting behavior, not around reasoning or accuracy.
What surfaced was a case-sensitivity problem. A capitalized character where the parser expected lowercase was enough to break the downstream handling, so the bot's reply never reached the user in usable form. The failure looked like a model defect from the outside but was really an interface contract violation. Once the tests pinned the exact reply format, the real source became obvious.
This is a familiar trap in production AI work. Teams ship a prompt, wire it to a parser, and treat the model as the only variable worth watching, when the contract between model output and application code is where most breakage lives. Running the same task against several models is one way to separate model behavior from integration behavior, and it is cheap compared with debugging in production. The Weave project treats that format as the thing under test, which is the right unit of analysis for a support bot.
The practical lesson is to regression-test the exact output format an app depends on, not just answer quality. A model that scores well on benchmarks can still fail a strict parser, and a model that scores lower can pass if its formatting is stable. Teams running support bots should keep format assertions in CI, version them alongside prompts, and re-run them whenever a model is swapped or updated.
The open question is how much of this burden belongs to the model providers. If formatting drift can silently break applications, should vendors guarantee stricter output contracts, or is that the integrator's job? For now, the answer sits with the developer, and the test suite is the only thing standing between a working bot and a capital letter.